Built
Selfbench
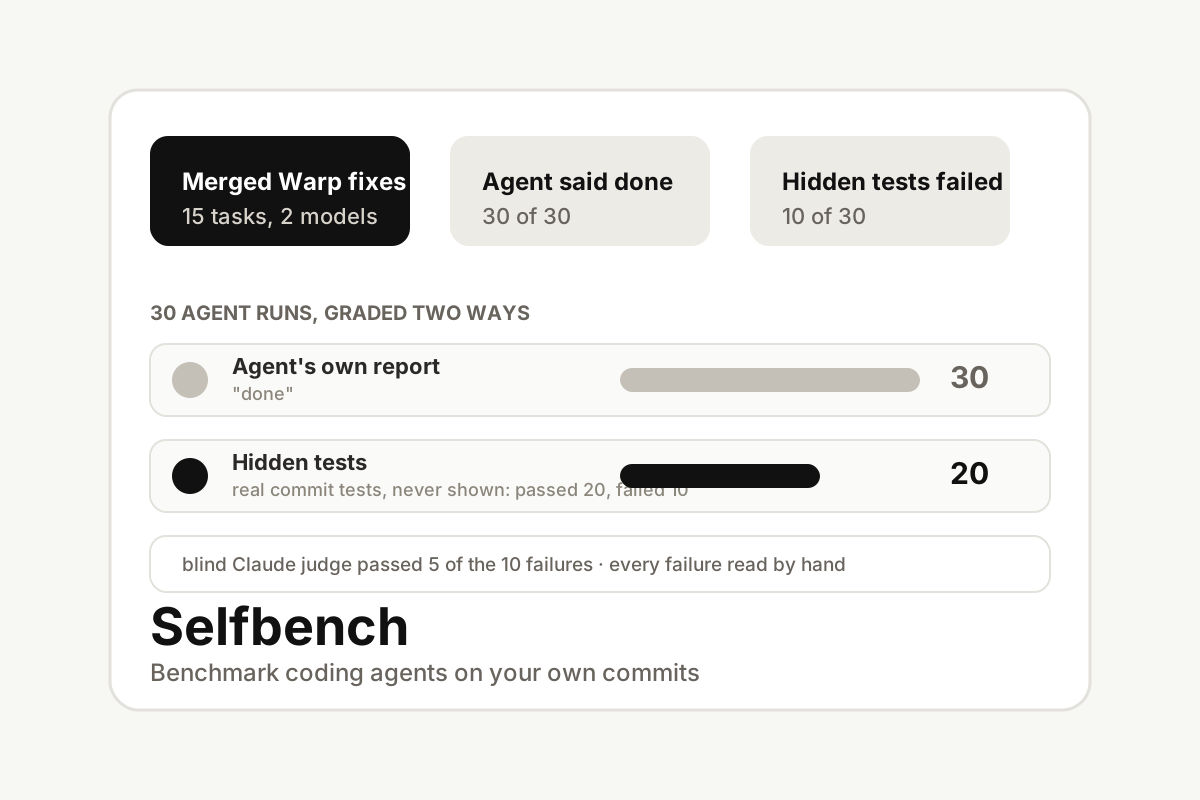
A benchmark that turns your own commits into tasks for coding agents and grades them with the tests the real commit added, which the agent never sees. Run on 15 fixes merged into Warp's open-source repo, Warp's Oz agent said done in 30 of 30 runs and failed the hidden tests in 10.
Why: Built because an agent saying done is not evidence. I read all 10 failures by hand, then ran a blind Claude judge on the same 30 runs: it passed 5 of the 10 failures, but it caught a stray 1,972-line backup file the tests never looked at. Neither check was enough alone.
PythonAI AgentsEvalsHidden Tests
GitHub